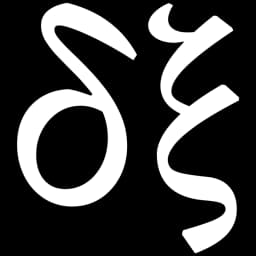
Gradient descent
Adjust parameters in a direction that locally reduces a loss.
Library note. Check the assumptions and further reading before applying a formula.
What Is This?
A loss function measures how poorly a set of parameters performs. Its gradient points toward the steepest local increase. Gradient descent takes a step in the opposite direction. The step size, eta, controls how far it moves. Repeat the calculation at the new point. The method uses local slope information, not a map of the whole landscape.
Try an example
For L(theta) = theta squared, the gradient is 2 theta. Starting at theta = 3 with a step size of 0.1, the next value is 3 minus 0.1 times 6, or 2.4.
Where it needs care
A step that is too large can increase the loss or diverge. Non-convex functions can have local minima and saddle points. A small training loss does not establish performance on new data.
Historical Context
Cauchy described an early steepest-descent method in 1847. Stochastic variants later made the approach practical for large datasets.
Real-World Applications
- Fit regression models and neural networks.
- Solve differentiable numerical optimisation problems.