Your cookie choices
Essential cookies keep your basket and sign-in working. Optional cookies help us understand visits and measure ads. Privacy details.
Essential cookies keep your basket and sign-in working. Optional cookies help us understand visits and measure ads. Privacy details.
Convert scores into probability distributions
AI-assisted explanation. It may contain errors; use a textbook or original source to check important details.
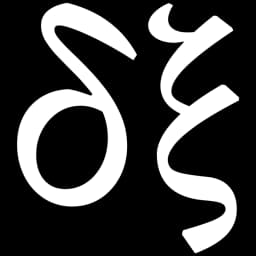
Softmax is a “turn scores into probabilities” machine. Imagine a model produces K raw scores (often called logits) for K possible choices—like how strongly it “leans” toward each label. Those scores can be any real numbers: negative, positive, huge, tiny, and they don’t have to add up to anything meaningful. Softmax takes that vector of scores z and converts it into a vector of numbers between 0 and 1 that sum to 1, so you can read them as probabilities. It does this in two steps: 1) Exponentiate each score: e^{z_j}. This makes every value positive and makes larger scores grow much faster than smaller ones (so the biggest score tends to dominate). 2) Normalize by dividing by the total across all classes: ∑_{k=1}^K e^{z_k}. This forces the outputs to sum to 1. In the equation, σ(z)_j is the output probability for class j. - is the input score for class j (a “vote” for that class). - K is the number of classes. - The denominator ∑_{k=1}^K e^{z_k} is the “total voting mass,” ensuring all probabilities add to 1. Intuition: softmax is like taking each class’s score, turning it into a positive “weight,” and then converting those weights into a probability distribution by dividing by the sum. If one score is much larger than the rest, its probability becomes close to 1; if scores are similar, probabilities spread more evenly. A key practical note: adding the same constant to every doesn’t change the output (because it cancels in numerator and denominator). This is why implementations often subtract max(z) for numerical stability.
Softmax has deep roots in 19th-century statistical physics: the Boltzmann/Gibbs distribution assigns probabilities proportional to (or ) when modeling how systems distribute themselves among states. That exponential-and-normalize pattern later reappeared in the social sciences as random utility / choice models (e.g., the Luce choice rule), and in statistics as multinomial logistic regression, where you model the probability of each class as an exponentiated linear score normalized across classes. Machine learning adopted softmax as neural networks began tackling multi-class classification: networks naturally produce unconstrained real-valued scores, and softmax provided a smooth, differentiable way to turn those scores into probabilities suitable for training with maximum likelihood / cross-entropy. In modern deep learning, softmax is also central in attention mechanisms and in reinforcement learning policies.
Pioneered by: No single person is universally credited with “discovering” softmax in its modern ML form. The core idea (exponentiate and normalize) traces back to Josiah Willard Gibbs and Ludwig Boltzmann in statistical mechanics (late 1800s). Closely related choice-model forms were developed by R. Duncan Luce (1950s) and Daniel McFadden (1970s) in econometrics, and the statistical framing appears in multinomial logistic regression. Deep learning popularized it as the standard output layer for multi-class classification.