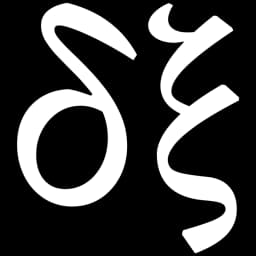
Statistical power
How likely a test is to detect a specified real effect.
Library note. Check the assumptions and further reading before applying a formula.
What Is This?
Power is the chance that a test rejects its null hypothesis when a particular alternative is true. That alternative must include an effect size: a test may find a large change reliably and miss a small one most of the time. Power depends on the test, sample size, noise and dependence. A non-significant result alone does not show that two options are equivalent.
Try an example
Before a trial, choose the smallest improvement that would matter in practice. Simulate data with that improvement and run the planned test on each sample. The share of samples that reject the null estimates power for that scenario.
Where it needs care
Also simulate the null to check the false-positive rate. Report the minimum effect the study could detect. Showing equivalence requires a pre-stated tolerance and an appropriate test, not simply a large p-value.
Historical Context
Jerzy Neyman and Egon Pearson formalised much of the modern testing framework in the 1930s, separating false positives from missed effects.
Real-World Applications
- Plan studies before collecting data.
- Explain what a negative result does and does not rule out.